Your AI
Transformation Partner.
Helping enterprises move from experimentation to measurable business impact through custom AI models, secure private cloud deployments, and automated MLOps infrastructure.
AI & ML Across Industries.
We don't build generic AI wrappers. We engineer vertical-specific machine learning architectures that deeply integrate into the unique operational workflows and compliance requirements of your industry.
Healthcare & Life Sciences
We deploy AI/ML solutions for healthcare that power secure diagnostic imaging analysis, automate clinical trial data extraction, and build secure clinical patient chatbots. Our computer vision models assist radiologists with anomaly detection, while our NLP pipelines extract structured data from unstructured medical records — all deployed inside sovereign VPC infrastructure with zero data leakage.
Financial Services & FinTech
Our machine learning models for financial services execute real-time credit risk scoring (Runwayfunds), automate unstructured financial document extraction (Oxane Partners), and power predictive deal-screening algorithms (Fundr). We build fraud detection pipelines, algorithmic underwriting engines, and LLM-powered financial chatbots that process sensitive PII under strict GDPR and enterprise data privacy standards.
Education & EdTech
We architect AI-driven personalized learning platforms (Qennex), smart campus analytics systems (Macmillan 360° Report), and intelligent document cognition engines for academic research institutions. Our ML models adapt curriculum difficulty in real-time based on student performance data, while our NLP systems automate grading and content summarization at scale.
Retail & E-Commerce
We build intelligent recommendation engines, dynamic pricing ML models, and visual search systems that transform retail operations. Our predictive analytics pipelines forecast inventory demand, optimize supply chain logistics, and power hyper-personalized shopping experiences. Each model is trained on your proprietary transaction data and deployed as a containerized microservice.
Logistics & Transportation
We deploy AI solutions for logistics that optimize route planning (Godide AI), predict demand fluctuations, and automate fleet management workflows. Our ML models process real-time GPS, weather, and traffic data to dynamically reroute shipments, reduce fuel costs, and predict maintenance schedules before breakdowns occur.
Enterprise SaaS & B2B
We embed intelligent AI copilots directly into B2B SaaS platforms, enabling end-users to query complex datasets using natural language. Our RAG-powered knowledge assistants, automated data pipeline orchestrators, and AI-driven analytics dashboards dramatically improve user retention and reduce support ticket volume by up to 60%.
We Don't Just Talk AI.
We Ship It.
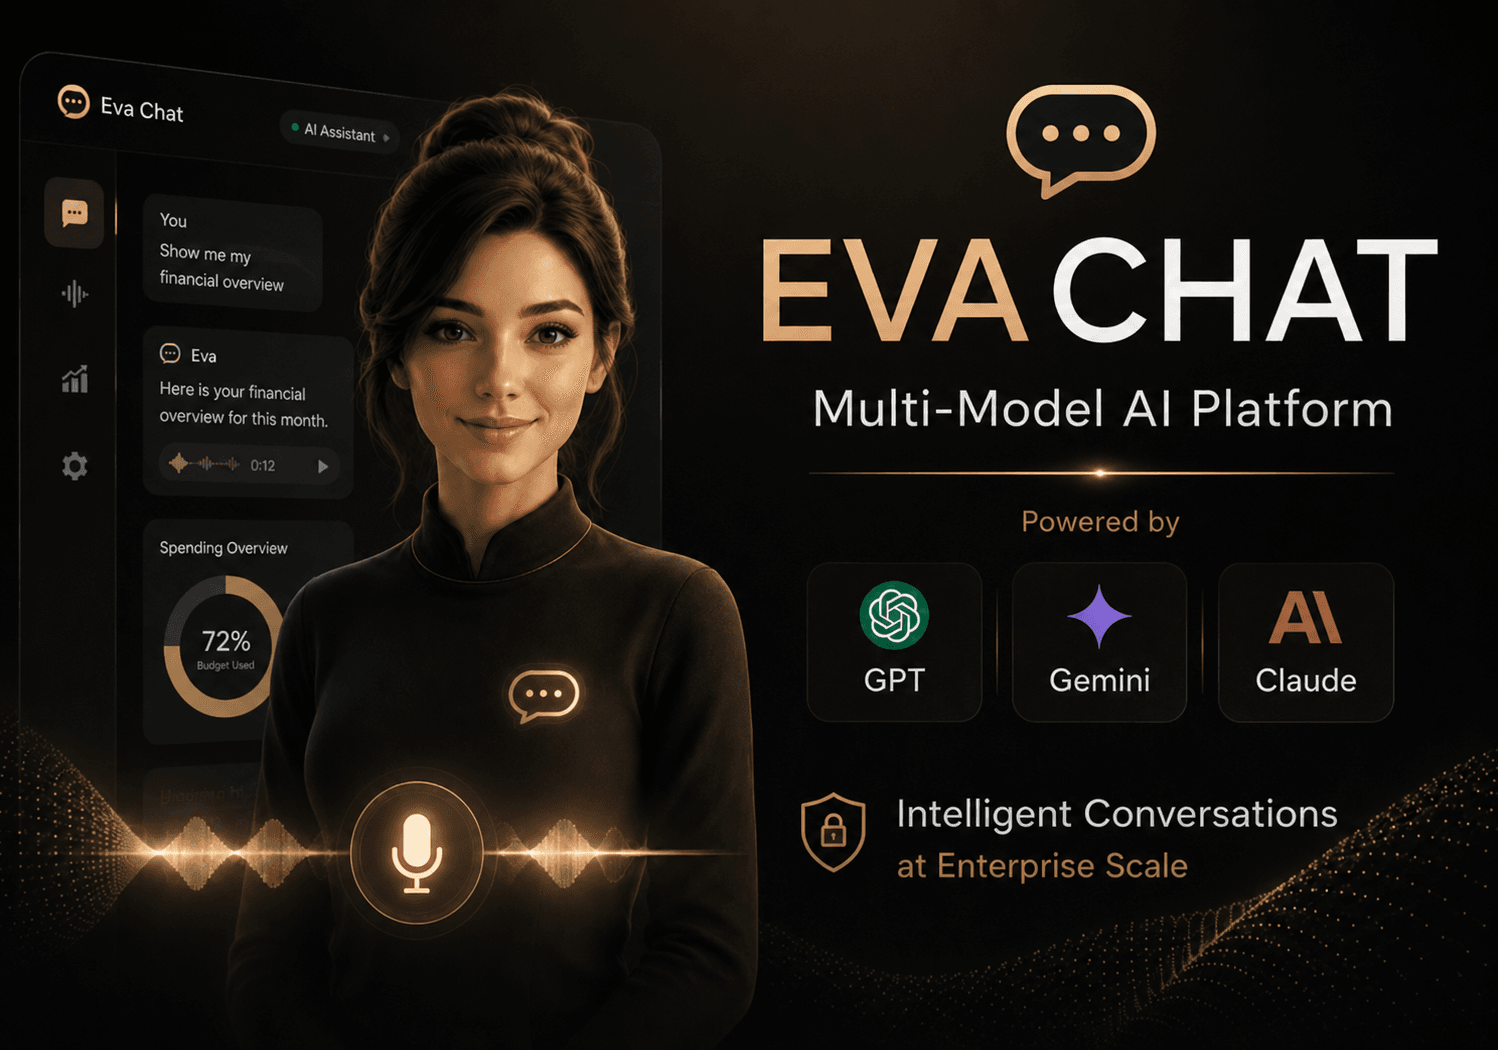
EvaChatBot — Financial AI Agent
Engineered a highly sophisticated conversational AI agent capable of navigating complex financial data, reducing manual audit and qualifying 200+ leads/month.
Built With

Document Extractor AI
Built a customized AI model to autonomously extract, structure, and verify critical unstructured data points from vast volumes of financial PDFs with 99.4% accuracy.
Built With

Fundr — Venture Intelligence AI
Developed a predictive AI infrastructure that assists in algorithmic deal screening, bringing quantitative rigor to early-stage venture capital workflows.
Built With
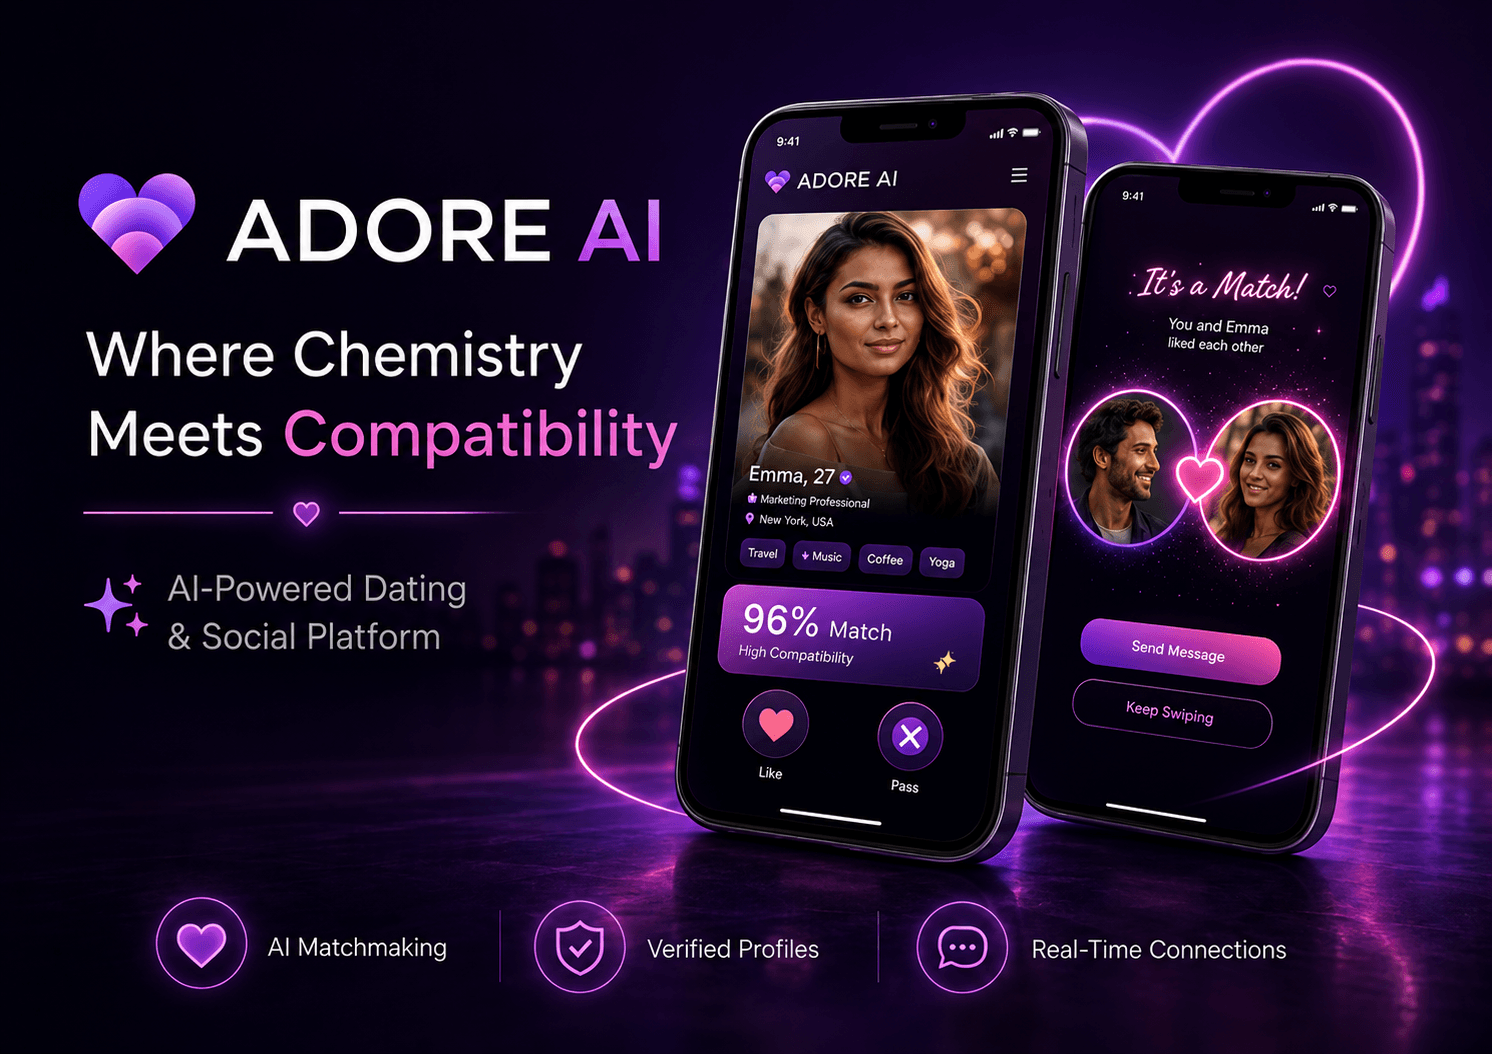
Adore AI Matchmaking
Architected a next-generation AI-powered dating and social connection platform with behavioral matching algorithms and natural interaction models.
Built With
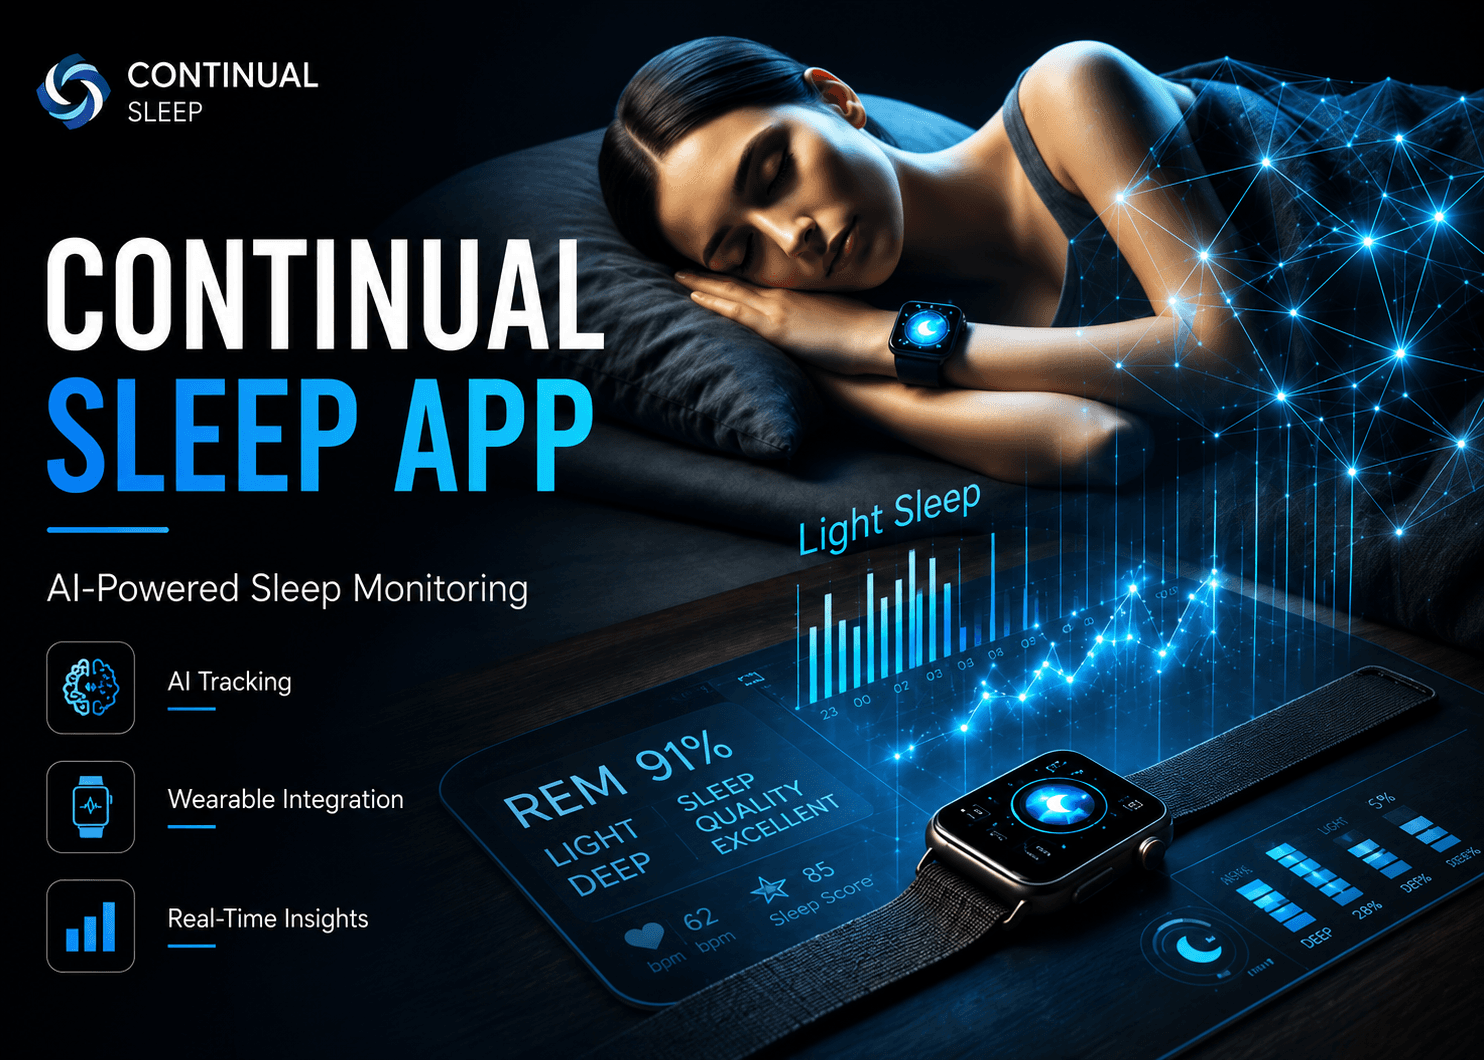
Continual Sleep AI Monitoring
Co-created an AI-powered sleep monitoring platform analyzing smartwatch sensor data to forecast sleep quality and deliver biometric insights.
Built With
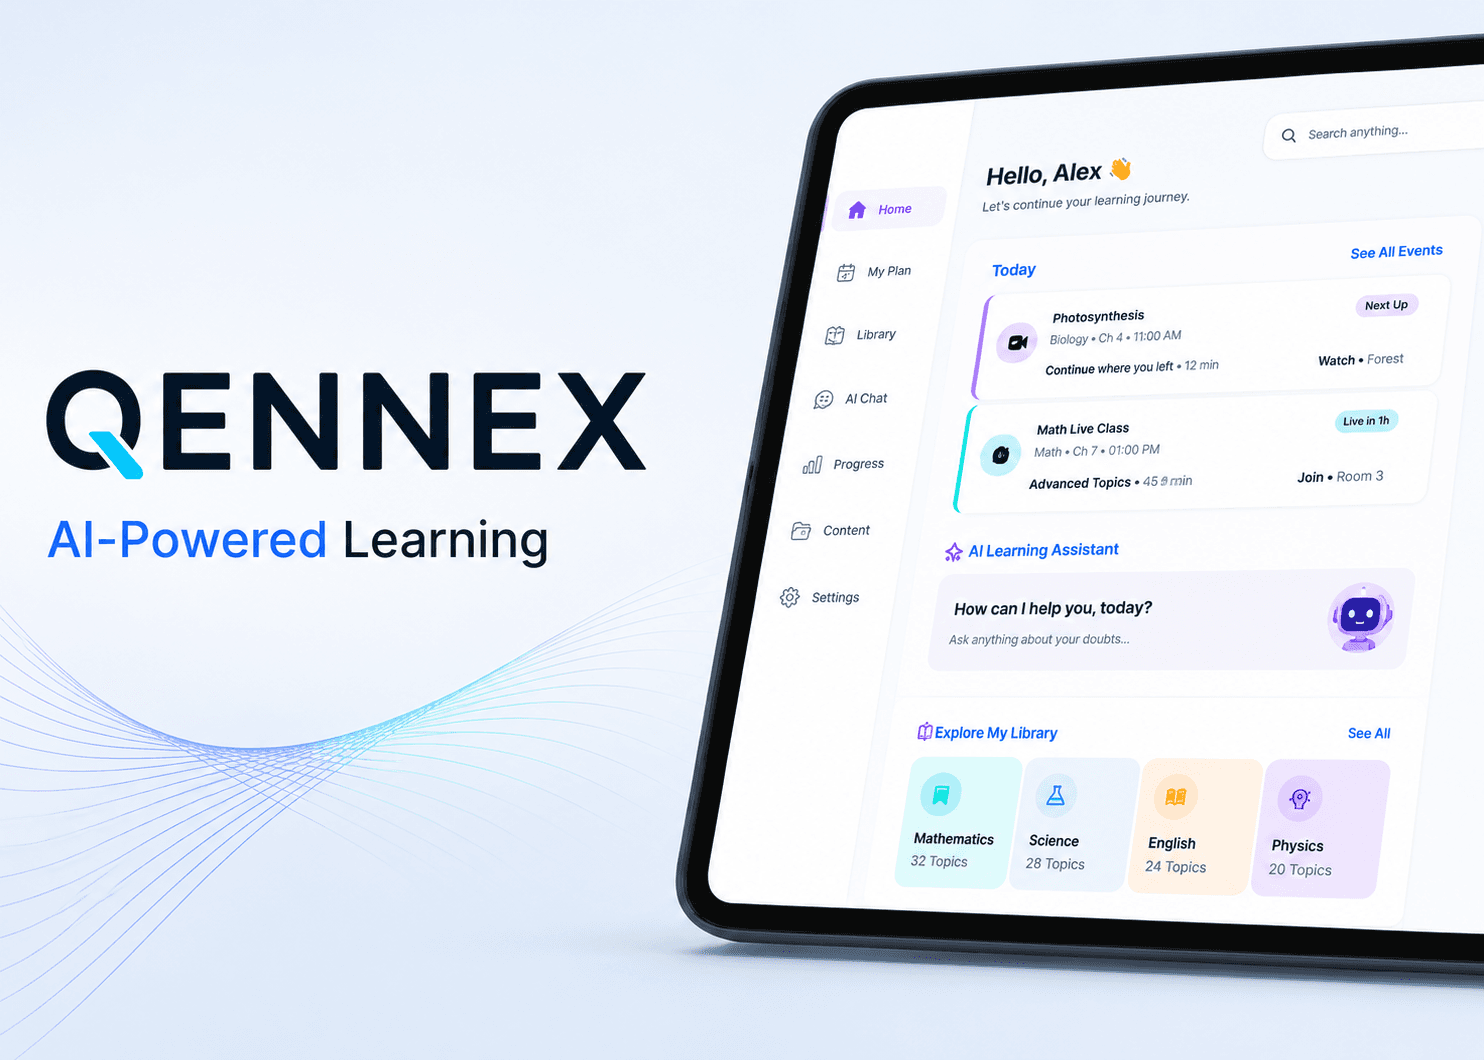
Qennex Adaptive AI Education
Architected an AI-driven personalized education platform that adapts curriculum difficulty dynamically based on real-time student performance metrics.
Built With
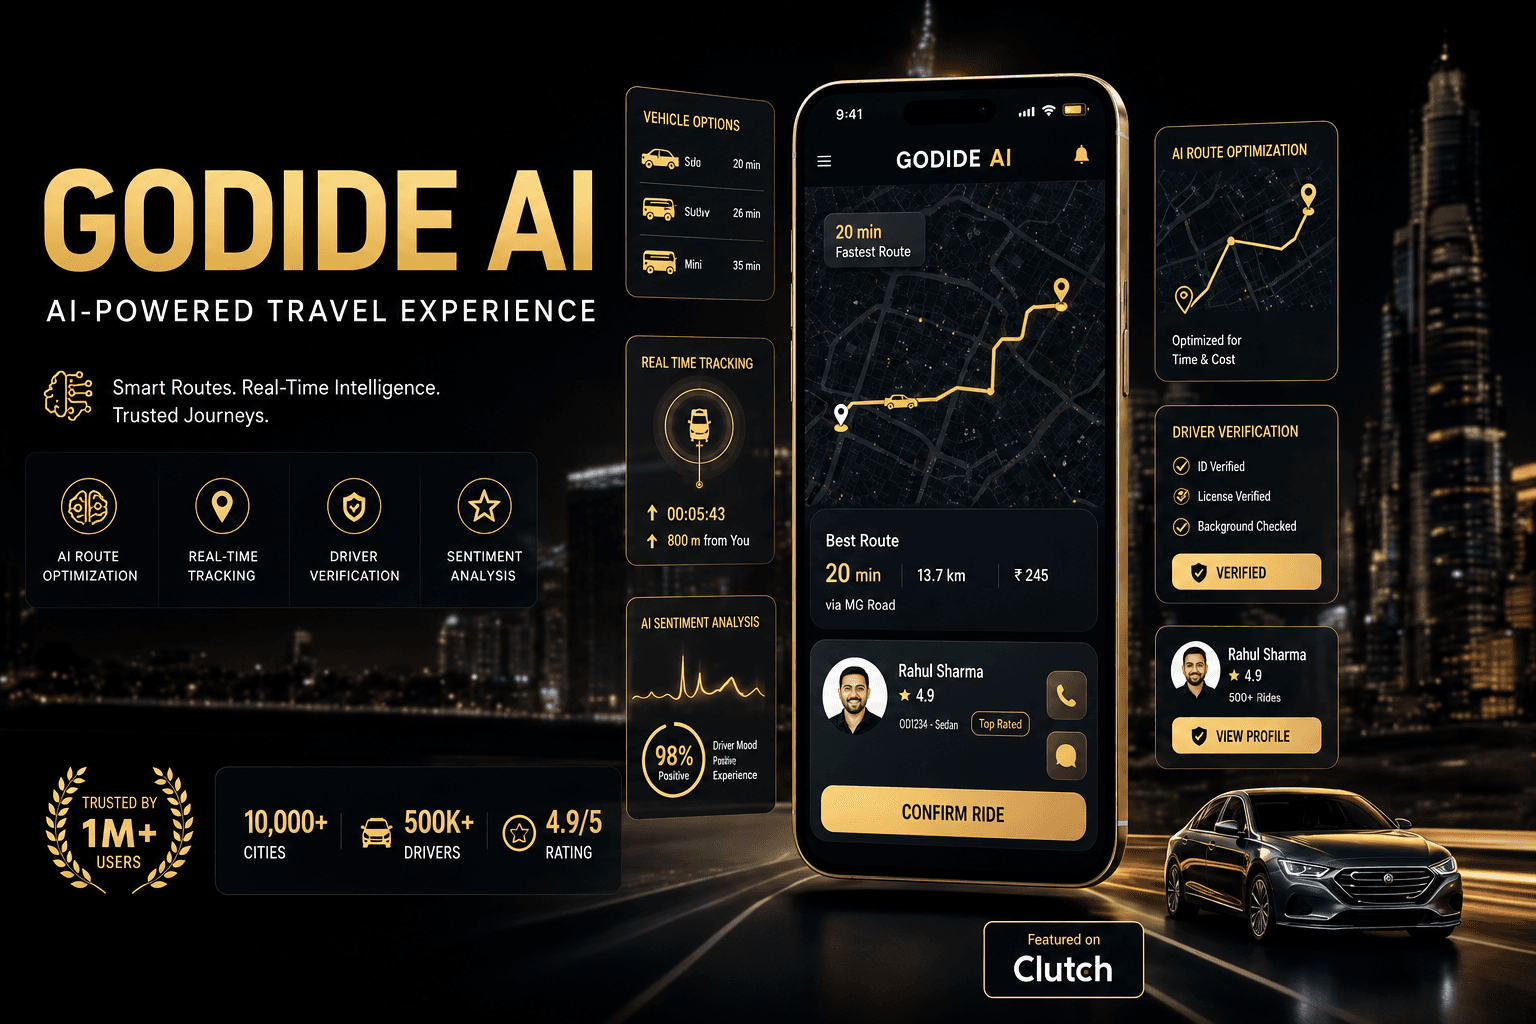
Godide AI Predictive Mobility
Designed predictive machine learning models that optimize route planning and dynamic ETA calculation for transportation networks across Africa.
Built With

Book PDF Extractor AI
Developed a document cognition microservice that parses complex book layouts, extracts tabular data, and generates semantic chunking for RAG pipelines.
Built With
The AI Delivery Framework.
We don't build in a black box. We accelerate enterprise deployments through our 12-week structured framework and proprietary pre-engineered software components.
Discovery
Data Viability Audit. We analyze schema volume and quality to ensure data is sufficient for model training.
Design
Model & Architecture Selection. Private VPC security planning and cloud topology mappings.
Prototype
Rapid POC Deployments. Training functional baseline models to validate algorithmic metrics.
Production
Inference Scaling. Microservice containerization (Docker/Kubernetes) and endpoint integrations.
Optimization
MLOps Orchestration. AWQ/GPTQ quantization, model drift telemetry, and automated retraining.
One AI Chat
A pre-engineered private LLM chat interface template. Connects securely to Pinecone/pgvector, bypassing conversational UI development to save up to 4 weeks of engineering time.
Kraft-Lens
A modular, low-latency visual detection framework. Optimized for real-time video feeds with pre-trained YOLO/ResNet wrapper hooks for custom annotation.
RAG Sync
Automated document OCR and chunking pipeline. Runs on cron-based schedules, autonomously parsing complex corporate files into structured vector databases.
The Deep Tech Powering Our Models.
We don't just build surface-level wrappers. We engineer high-performance inference pipelines, private vector architectures, and self-hosted model deployments built for enterprise uptime.
Open-weight on-prem models
LLM orchestration framework
High-performance vector database
Retrieval-Augmented Generation
Reference Architecture.
We don't build black boxes. We architect transparent, Zero-Egress ML pipelines deployed directly into your existing cloud infrastructure (AWS/Azure/GCP).
Enterprise AI, Explained.
Clear, authoritative answers to the technical and business questions enterprise leaders ask us most.
Artificial Intelligence (AI) is the broad discipline of building software systems that can perform tasks typically requiring human intelligence — such as understanding natural language, recognizing images, making decisions, and generating content. Machine Learning (ML) is a specific subset of AI where systems learn patterns directly from data rather than being explicitly programmed with rules. For example, a rule-based fraud detection system that checks 'if transaction > $10,000, flag it' is traditional software. A machine learning fraud detection system analyzes millions of historical transactions to independently discover complex fraud patterns that no human could manually code. At Kraftors, we engineer both — from custom-trained predictive ML models (XGBoost, Random Forest, Deep Neural Networks) to sophisticated AI systems like private LLMs, RAG architectures, and autonomous conversational agents. The key distinction for enterprise buyers: AI is the capability, ML is the technique, and we deliver both as production-grade, sovereign software that you fully own.
Retrieval-Augmented Generation (RAG) is an AI architecture pattern that solves the single biggest problem with Large Language Models in enterprise settings: hallucination and data staleness. A standard LLM (like GPT-4 or Llama 3) is trained on a static dataset and has no knowledge of your company's proprietary data — your contracts, financial reports, internal policies, or customer records. RAG solves this by connecting the LLM to a live vector database containing your corporate knowledge base. When a user asks a question, the system first retrieves the most relevant documents from your private data store (using semantic similarity search via embeddings), then feeds those documents as context to the LLM, which generates an answer grounded in your actual data rather than its general training. At Kraftors, we build production-grade RAG pipelines using LangChain, Pinecone/pgvector, and open-weight models like Llama 3, deployed entirely inside your VPC. We also engineer Auto-Tuning RAG Cron Jobs that automatically re-index your knowledge base on a schedule, ensuring the AI always has access to the latest documents without manual intervention. This architecture is the foundation of our Document Extractor AI (Oxane Partners) and EvaChatBot (MyStartup CFO) deployments.
The cost of custom AI/ML development varies significantly based on the complexity of the data pipeline, the type of model required, the number of integrations, and the security constraints of your organization. At Kraftors, we structure our engagements into three transparent phases to eliminate budget uncertainty. Phase 1 is a Data Viability Audit (Weeks 1-2): we analyze your existing datasets, assess data quality, identify PII compliance risks, and produce a hard ROI projection document with a fixed scope and cost. Phase 2 is the Production MVP Build (Weeks 3-8): we deploy a dedicated pod of ML architects to train your custom model, containerize it via Docker/Kubernetes, and integrate it into your existing infrastructure via secure REST/FastAPI endpoints. Phase 3 is Production MLOps (Weeks 9-12): we set up automated retraining pipelines, model drift monitoring, and 24/7 observability. A focused internal AI copilot or document extraction pipeline typically starts in the low five figures, while a large-scale predictive analytics platform or multi-model RAG system for an enterprise requires a larger strategic investment. We offer tailored scoping sessions to define exact architectures and budgets before any code is written.
Yes — and this is one of Kraftors' core strengths. We do not require you to rip and replace your existing infrastructure. Every AI/ML model we build is deployed as an independent, containerized microservice using Docker and orchestrated via Kubernetes. These models are exposed securely through FastAPI or REST endpoints that your existing frontend, ERP, CRM, or legacy monolith can consume with a simple HTTP call. For example, if you have a 15-year-old Java-based claims processing system, we deploy a document extraction ML model as a separate Docker container that accepts PDF uploads via a secure API endpoint and returns structured JSON data. Your legacy system makes a single POST request and receives clean, extracted data — no architectural changes required on your end. We support cloud-agnostic deployment across AWS SageMaker, Azure ML, Google Cloud Vertex AI, or fully on-premise GPU clusters. Our architecture ensures zero vendor lock-in: you own the model weights, the inference code, and the deployment infrastructure permanently.
Model Quantization is the process of reducing the computational precision of a neural network's weights — typically from 32-bit floating point (FP32) to 4-bit or 8-bit integers — to dramatically reduce memory requirements and inference latency without significantly impacting accuracy. This technique is critical for enterprise AI deployment because it allows organizations to run powerful Large Language Models on standard CPU-only servers instead of expensive GPU clusters, reducing infrastructure costs by 60-80%. At Kraftors, our Applied AI Research team specializes in production quantization using techniques like AWQ (Activation-Aware Weight Quantization) and GPTQ (Generative Pre-trained Transformer Quantization), deployed via vLLM and TensorRT inference servers. We have successfully quantized full-size LLMs to run on low-computation hardware while maintaining over 95% of the original model's accuracy. This capability is essential for organizations deploying private, on-premise AI systems where GPU availability is limited or cost-prohibitive — a core component of our Sovereign AI guarantee.
Data security is not an afterthought at Kraftors — it is the foundation of our entire AI engineering practice. We are ISO 27001:2022 certified, and every AI system we build follows our Zero-Egress Architecture principle: your data never leaves your secure environment. Specifically, we implement four layers of protection. First, PII Tokenization: all Personally Identifiable Information is scrubbed, hashed, or tokenized in the ETL pipeline before it ever touches a training dataset, ensuring GDPR compliance and strict enterprise data protection standards. Second, Private Model Deployment: we deploy open-weight LLMs (Llama 3, Mistral) directly inside your VPC or on-premise servers. Unlike OpenAI or Anthropic API calls, your data never traverses the public internet. Third, Secure Inference APIs: production models are wrapped in rate-limited, authenticated FastAPI microservices with Role-Based Access Control (RBAC) at the API level, protecting model weights from reverse engineering and adversarial extraction attacks. Fourth, Model Drift Monitoring: we deploy automated observability tools (DataDog, Prometheus) that continuously track statistical drift in model performance and trigger CI/CD retraining pipelines before accuracy degrades. This architecture is what enables us to serve regulated industries like healthcare (clinical record confidentiality), finance (transactional privacy), and government (sovereign cloud requirements).
Computer Vision (CV) is the branch of AI that enables machines to interpret and make decisions based on visual data — images, video feeds, satellite imagery, and medical scans. In enterprise settings, CV goes far beyond simple image recognition. At Kraftors, we deploy production-grade computer vision systems using frameworks like YOLOv8 for real-time object detection, OpenCV for visual data processing, PyTorch Vision for deep learning on images, and CUDA for GPU-accelerated inference. Our proven CV implementations include real-time object detection in video feeds (Climb Track), automated sports video annotation for football match analysis, and body-type image classification for retail applications. Enterprise use cases we specialize in include: manufacturing defect detection on assembly lines using CNN-based anomaly detection, retail visual search that allows customers to find products by uploading photos, medical imaging analysis for radiology and pathology, and IoT-connected camera systems for warehouse automation and security monitoring. Each CV model is containerized and deployed via our standard MLOps pipeline with GPU acceleration, ensuring sub-millisecond inference latency at scale.
Fine-tuning and RAG (Retrieval-Augmented Generation) are two fundamentally different approaches to customizing a Large Language Model for enterprise use, and choosing the wrong one can waste months of engineering effort. Fine-tuning modifies the model's internal weights by training it on your specific dataset. This permanently changes how the model 'thinks' and is ideal for teaching the model a new skill, tone, or domain-specific reasoning pattern. However, fine-tuning is expensive (requires GPU compute), slow (days to weeks of training), and creates a static model that doesn't automatically update when your data changes. RAG, by contrast, keeps the base model untouched and instead connects it to a live knowledge base via vector embeddings. When the model needs to answer a question, it first retrieves relevant documents from your data store and uses them as context. RAG is cheaper to deploy, updates instantly when you add new documents, and provides traceable citations for every answer. At Kraftors, we recommend RAG as the default architecture for most enterprise use cases — it is faster to deploy, easier to maintain, and provides built-in explainability. We reserve fine-tuning for cases where the model needs to learn a fundamentally new behavior (e.g., generating domain-specific code, understanding proprietary notation systems, or adapting to a highly specialized communication style). Many of our production systems use a hybrid approach: a fine-tuned base model enhanced with RAG retrieval for the best of both worlds.
READY TO DEPLOY
Submit a Technical
Briefing.
If you aren't ready for a Calendly call, submit your project scope securely. One of our AI architects will review it and respond with a technical assessment within 12 hours.
Secure Channel
hello@thekraftors.com
Immediate Protocol
Book a Direct Consultation